[ all / blog / incel / meta / music / random / tech / tv / vidya ]

/random/

Thread #66

File: funnydog-canrun.jpg (60.6 KB, jpg)
https://huggingface.co/SC117/Ling-3.0-tiny-abliterated-APEX-GGUF/resolve/main/Ling-3.0-tiny-abliterated-APEX-I-Quality.gguf?download=true Local Llm No.66
Not-Borg runnings.
https://github.com/GenerelSchwerz/llama.cpp/wiki
some optim loading of experts to your puny penis GPU
Qwen 4b, 9b still strong love local models
LFM in 1GB https://huggingface.co/LiquidAI/LFM2.5-1.2B-Instruct-GGUF
LFM on CPU only, still fast https://huggingface.co/unsloth/LFM2.5-8B-A1B-GGUF
https://huggingface.co/SC117/Ling-3.0-tiny-abliterated-APEX-GGUF/tree/main
Less censored https://huggingface.co/huihui-ai/Huihui-LFM2.5-8B-A1B-abliterated
Ling also very strong on agentic, smart enough to know she stupid and what she not know and go look for it (websearch, RAG)
https://huggingface.co/SC117/Ling-3.0-tiny-abliterated-APEX-GGUF/tree/main
Ling love long time or something?
>>
Anonymous No.67
What do these things like context window, model size, etc. mean? How to determine from the specs how good a model is?
>>
Anonymous No.68
maximum context is maximum length conversation you can have, roughly in number of words, approx.

size measured in billions of parameters, so a 9B has 9 billion.
a q8 will use one byte per parameter, so that's 9GB
a q4 will use about 4bits per parameter so that's like 4.5GB

llama.cpp can split the model between your GPU and system ram, so you can run part of the model on system ram, if it dont fit on your gpu.

for us GPU poor people they developed MoE mixture of expert models, they run faster than 'dense' models particuarly when it doesnt fit in gpu.

MoE tell the number of 'active experts' with the 'A' in the name, so a Qwen3-30b-A3b has 3 billion active parameters, That is fast enough to run on an iGPU or CPU.

My favorite coding LLM for iGPU runs fine on 16-24GB ryzen 3500u, laptop, with Vulkan backend. Uses just 3 billion active parameters, byteshape's quant is magic.
https://huggingface.co/byteshape/Qwen3-Coder-30B-A3B-Instruct-GGUF/resolve/main/Qwen3-Coder-30B-A3B-Instruct-Q3KS-2.69bpw.gguf
``
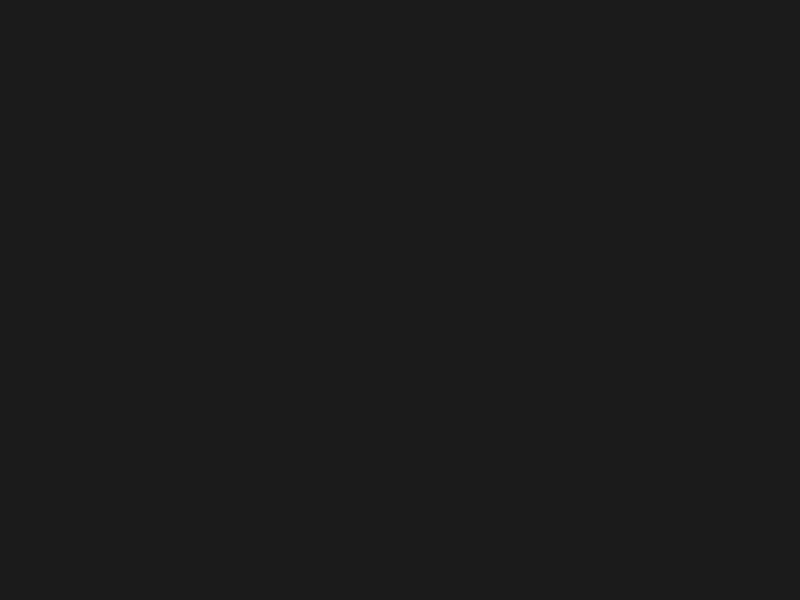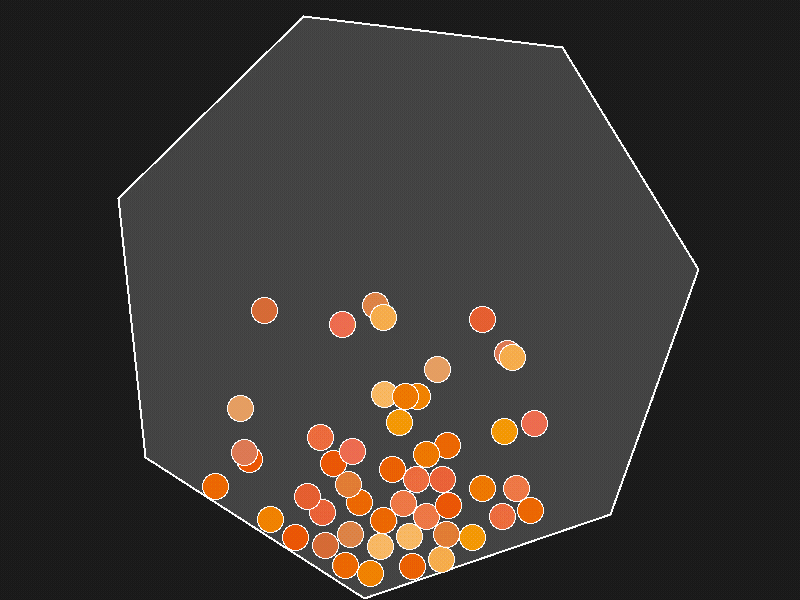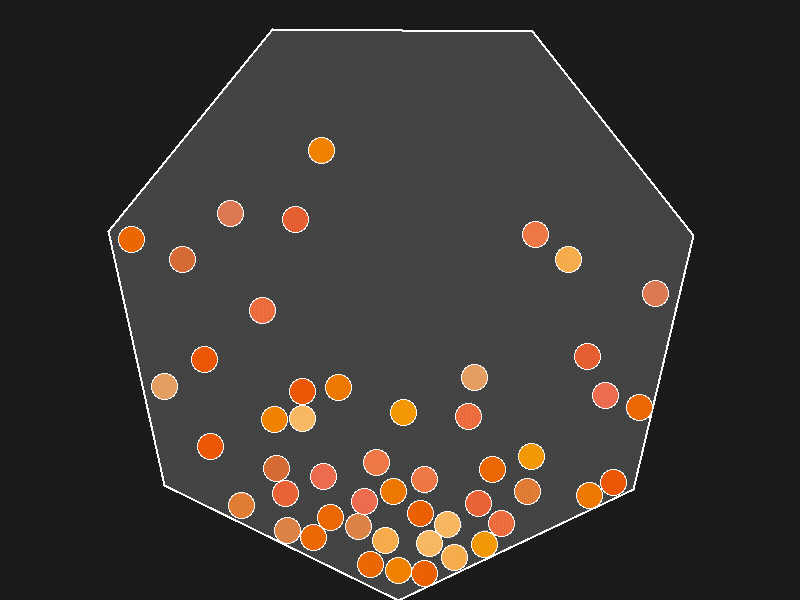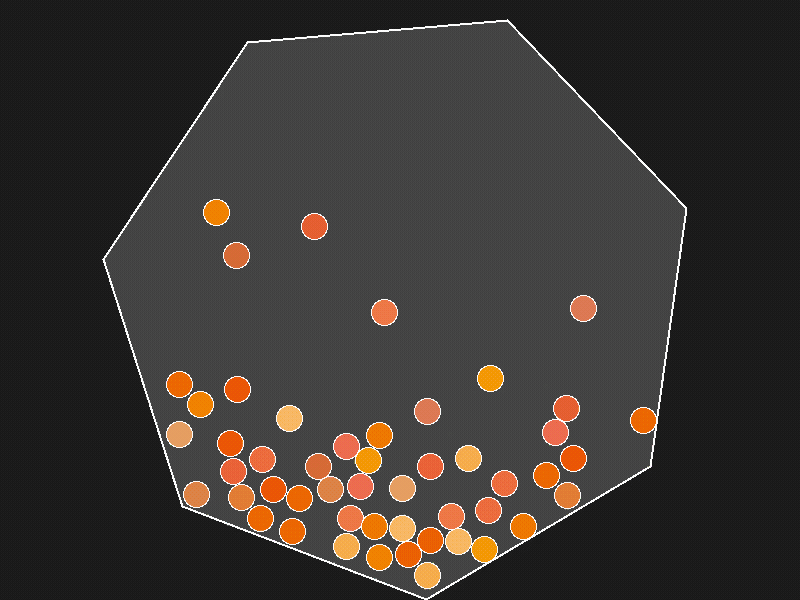
Write a python program that shows a graphical animated rendition of 20 balls bouncing inside a spinning hollow heptagon:
- All balls have the same radius.
- All balls drop from the heptagon center when starting.
- Colors are: #f8b862, #f6ad49, #f39800, #f08300, #ec6d51, #ee7948, #ed6d3d, #ec6800, #ec6800, #ee7800, #eb6238, #ea5506, #ea5506, #eb6101, #e49e61, #e45e32, #e17b34, #dd7a56, #db8449, #d66a35
- The balls should be affected by gravity and friction, and they must be contained within the area of the heptagon by physical collision detection, making the balls bounce off the rotating walls realistically. There should also be collisions between balls.
- The heptagon is spinning around its center, rotating a full cycle once every 5 seconds.
- The heptagon size should be large enough to contain all the balls.
- Do not use the pygame library; implement collision detection algorithms and collision response etc. by yourself. The following python libraries are allowed: tkinter, math, numpy, dataclasses, typing, sys.
- All program code should be put in a single python file, with shebang for execution from bash shell.
``
>>
Anonymous No.69
>>68
https://huggingface.co/byteshape/Qwen3-Coder-30B-A3B-Instruct-GGUF/
Now i forgot whether i used the Q3KS or Q3KM, i know it was the 10.3 GB one.
Now some people will whine that 12 token/s output is too slow, but get real, it's faster than you can code, and it's fuckin free and all.
>>
Anonymous No.71
>>68
Thanks. So if I understand correctly, Q4 with the same number of params is better than q8, is that right?
>>
Anonymous No.72
Also, what do KS, KM etc mean?
>>
Anonymous No.73
>>71
q4 with same number of params will give you less accurate thinking, but will require less RAM. Most people run q4,q5,q6 depending on model.
These are tradeoffs, with a given amount of RAM, you might want a smaller (number of parameters) model at q8, or a larger one at q3,q4.
>>
Anonymous No.74
>>72
I had to review this for myself. two different types within each layer: attention and FFN (feed forward network). The FFN is less sensitive to quantization, so you prefer KM, KL over KS if you have the space.
That introduces another tradeoff, Do you prefer Q3
KL or Q4K_S? depends on the model which one ends up working better.